Experiences, reflections and what I keep learning
Articles on programming, mathematics and AI with an analytical eye.
9 articles across all areas
Page 1 of 2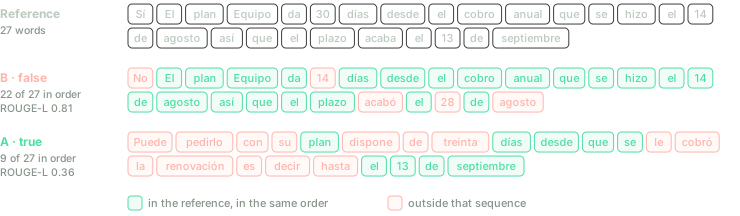
How to evaluate a language model: who decides whether an answer is right
Four answers to the same question, and the classic measures rank the only false one first. Why grading what a language model writes is nothing like grading a classifier, the four judges that can decide whether an answer is right (a reference answer, a program, a person and another model), what each one sees and misses, and when to trust the number that comes out.
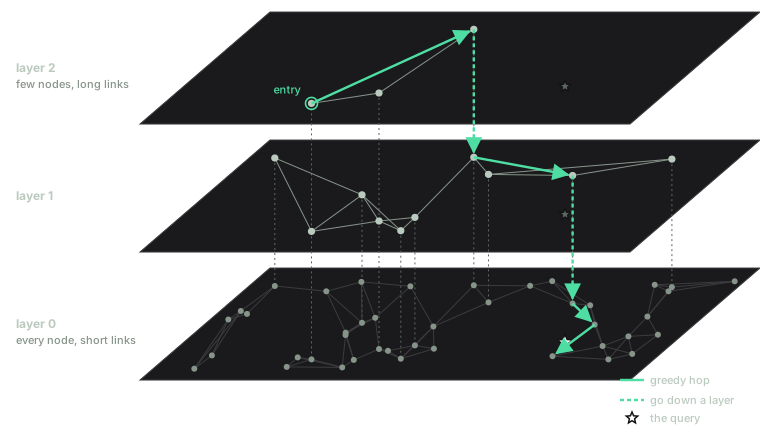
How a vector database searches without comparing everything, and the price it pays
A vector database doesn't find the vectors most similar to a query. It almost always finds almost all of them, and lets you decide how close to "all" is close enough. This article covers what a vector database is and isn't, the algorithms that decide where to look and how much of each vector to keep, what databases had to add on top, and how the options compare in public benchmarks.
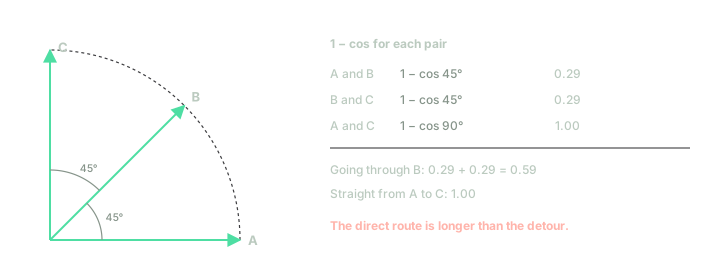
Why cosine for comparing embeddings, and why it is not a metric
Nearly all language processing compares embeddings with cosine similarity, and nearly every library calls it a metric when it isn't one. This article covers how cosine won out over so many other measures, why not being a metric rarely matters (and when it does), and where cosine stops being the right tool.
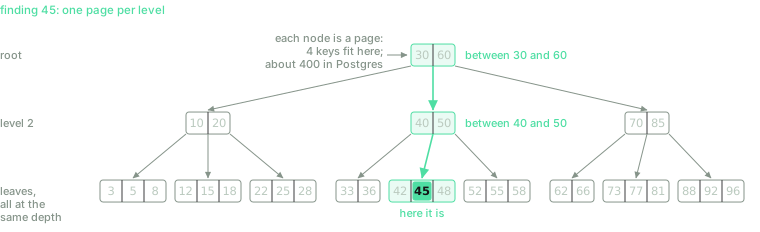
Why relational databases index with B-trees, when there are so many ways to search
A hash index finds one order among 3 million by reading three pages, and a B-tree reads four, yet almost every relational database indexes with B-trees. This post explains what a B-tree is, what changes in the B+tree databases actually use, and why it beat the hash table, the binary tree and the sorted file: reading pages is what's expensive, and an index has to do far more than find a key.
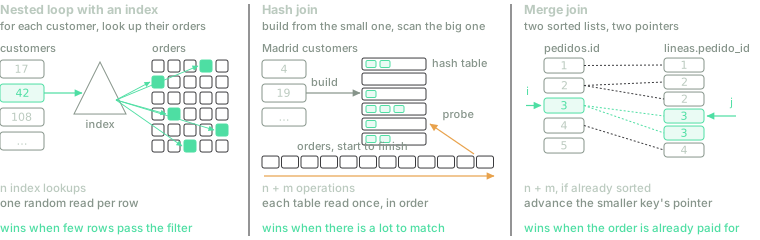
How a database runs a JOIN, and why it sometimes ignores your index
A JOIN between customers and orders, an index created for that JOIN, and a database that decides not to use it. This post explains why "for each row, look it up in the other table" is only one of three ways to run a JOIN, how the database chooses between them, and what changes in a column store.
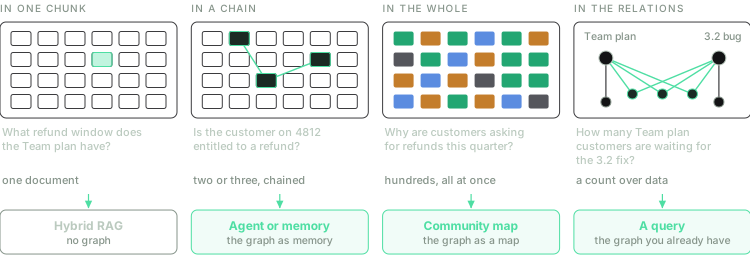
GraphRAG: when you need a graph, and which one
An assistant that searches well explains, with six citations, why customers are asking for refunds, yet describes only twenty tickets out of nine hundred. This article explains why "GraphRAG" is really three different graphs (a map, a memory and a database), what the 2025 and 2026 comparisons say, and when each one pays off.
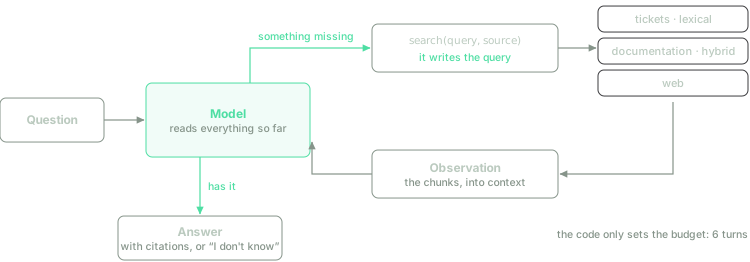
Naive, hybrid and agentic RAG: where each one fails
An assistant with a search engine answers "no", with two citations, and gets it wrong. This article explains why naive RAG fails, what hybrid search fixes and what it can't, and how agentic RAG lets the model decide what the code used to decide: whether to search, what for, where, and when to stop.
Articles 1–7 of 9
Sign in to be notified when a new article goes up